Connect with us
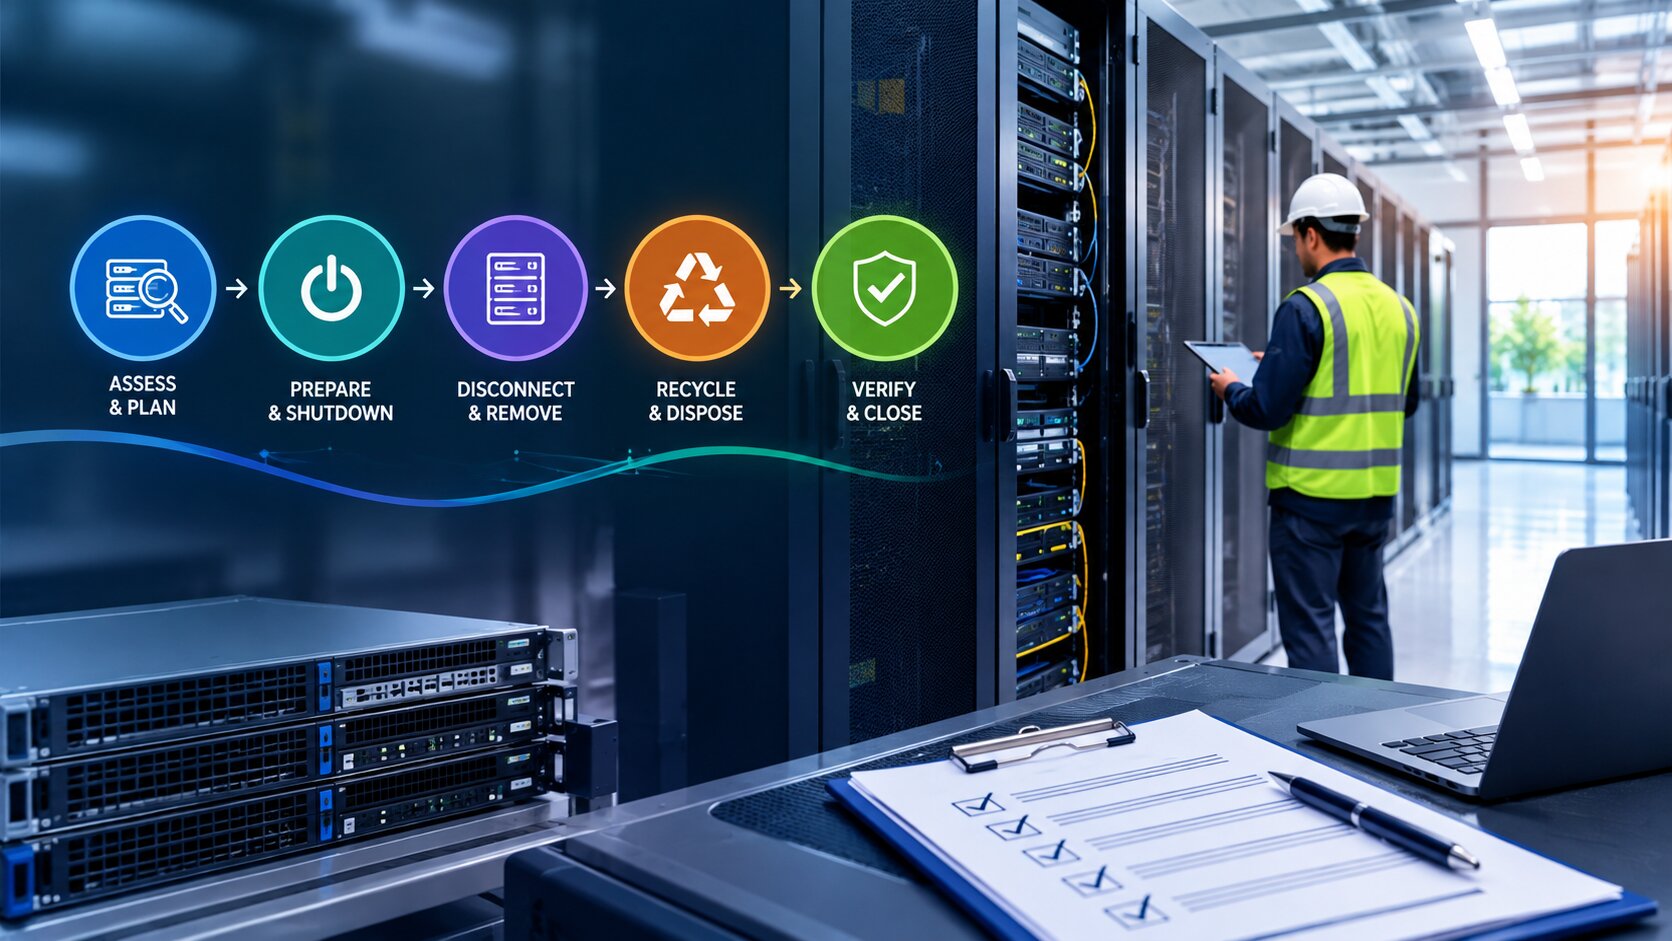
How to Plan a Full Data Center Decommission, Phase by Phase
A colocation contract ends on the last day of March. The hall holds roughly forty racks, a mix of owned and leased gear, about nine hundred drives, two tape libraries nobody has touched since the last audit, and a cage that has to go back to the provider in the condition the contract describes. Somebody in that organization is now the decommissioning lead, probably by accident, and the date is not moving.
That is the shape of most decommissioning projects I have been called into. The date arrives from a lease, a merger, a cloud migration that finally finished, or a landlord who has other plans for the building. Everything else in the project has to be sequenced backwards from that date, and the sequencing is where teams lose money and lose sleep. The work itself is not complicated. Getting it in the right order, with the right approvals in hand before each step, and keeping everyone aligned as the project moves forward is the hard part.
What follows is the phase order that actually holds up, along with the specific places I have watched projects go sideways.
What a Decommission Covers, and Where the Scope Ends
Data center decommissioning is the controlled shutdown, removal, sanitization, and disposition of the equipment in a facility or a portion of one, ending with documentation that proves what happened to every asset. It is a project with a defined finish line, not an operations task.
Two terms matter before you start planning, because contracts and vendors use them loosely.
IT asset disposition, usually shortened to ITAD, is what happens to the hardware after it leaves the rack: testing, grading, data sanitization, resale, recycling, or destruction, with records for each unit.
Chain of custody is the documented handoff trail for every asset from the moment it is pulled to the moment it is destroyed, resold, or redeployed. If your chain of custody has a gap, you do not have an audit trail; you have a story.
Scope also has an edge that people forget to draw. A decommission usually covers IT hardware, structured cabling, and the mechanical and electrical equipment you own or are contractually obliged to remove. It usually does not cover base building systems, and in a colocation cage it may not cover much of the facility at all. Read the restoration clause in the contract before you scope anything, because that clause decides whether you are pulling servers or pulling raised floor.
Phase 1: Lock the Date, the Scope, and the People Who Sign
Nothing else can be planned until three things are fixed in writing: the hard exit date, the physical and contractual boundary of what is being removed, and the named people who can approve a shutdown, a data destruction order, and an asset leaving the building.
That last item is the one that gets skipped. Teams build beautiful inventories and detailed migration waves, then stall for three weeks in month two because nobody established who is allowed to authorize the destruction of a drive that might hold regulated records. Approval authority is not a formality. On a real project it is the critical path.
It also helps to establish a clear communication process at this stage. A decommission touches infrastructure, security, application owners, facilities, finance, vendors, and sometimes compliance teams. If updates and approvals are scattered across email threads and informal conversations, it becomes harder to know which decision is current. Use a shared communication channel or workspace where the project team can track decisions, dependencies, and outstanding approvals.
Work backwards from the exit date and mark the fixed constraints first:
- ackwards from the exit date and mark the fixed constraints first:
- Contract dates: lease end, restoration deadline, colocation notice periods, and any early termination penalty that changes the economics.
- Vendor lead times: shredding trucks, freight, riggers, and lift equipment book out further than most people expect, especially at quarter end.
- Audit and reporting cycles: if a financial close or a compliance audit lands inside your window, plan around it rather than through it.
- Application freeze windows: change control will block your shutdowns during peak trading, open enrollment, or whatever the seasonal equivalent is in your industry.
Write down who owns each phase and who signs at each gate. Then circulate it, because half the delays in this kind of project come from a person discovering on a Tuesday that they were supposed to have approved something the previous Thursday.
Phase 2: Build an Inventory You Can Reconcile Against Later
Your configuration management database is wrong. I say that flatly because I have never once seen it be right at the start of a decommission, and planning as though it might be right is the most expensive optimism available to you.
The inventory you need for a decommission is not the inventory you use for operations. It has to be serial-level, it has to record ownership status, and it has to be something you can reconcile against destruction certificates a year later when an auditor asks. Build it from three passes that disagree with each other on purpose: an automated discovery scan, a physical walk of every rack with a scanner, and a pull of the asset register from finance and procurement.
Capture for every unit:
- Serial number, make, model, rack and U position.
- Ownership: owned, leased, financed, or vendor-supplied under a maintenance agreement.
- Whether it contains storage media, and what kind. Drives and tape hold data. Graphics cards, processors, and memory modules do not persistently store user data, and treating them as though they do will cost you resale value for no security benefit.
- Current workload status, including whether anything is still running on it.
That last field turns up things nobody expected. The United States Environmental Protection Agency's ENERGY STAR program cites research finding that around 30 percent of physical servers in data centers were comatose, meaning powered on and drawing energy while doing no useful work, with one facility discovering that more than half of its servers fell into that category. On a decommission this is good news rather than bad, because comatose machines can be shut down early and pulled out of the migration plan entirely, but you only find them if the inventory asks the question.
The mistake here is starting the inventory too late. It takes longer than anyone budgets, it drives the migration plan, the freight plan, and the disposition plan, and every downstream estimate you produce before it is finished is a guess.
Phase 3: Migrate, Then Wait, Then Verify
Migration planning belongs to the application owners, not to the decommissioning lead, but the decommission schedule lives or dies on it. Your job in this phase is to sequence it and to insist on a soak period.
Map dependencies first. Not the documented dependencies, the actual ones, which you find by watching network flows rather than reading a diagram somebody drew in 2019. Group systems into migration waves that respect those dependencies, then schedule the waves with the riskiest and most poorly understood systems first, while you still have runway to fix things.
After each wave completes, leave the old environment powered and intact for a defined soak period. Two to four weeks is common. During that window, you are watching for the failures that only show up on a month-end job, a quarterly batch, or a reporting run that nobody remembered existed. Verify your backups independently during the soak, and confirm that restores actually work from the new location rather than assuming that a green backup job means a recoverable system.
Keep the migration team and decommissioning team connected throughout this period. A failed job, unexpected dependency, or change in the migration schedule needs to reach the people responsible for physical removal before equipment is touched.
The step people get wrong is starting physical removal during the soak period because the schedule is tight. Once a rack is stripped, there is no rollback, and a failed cutover with no rollback is how a decommission project turns into an outage postmortem.
Phase 4: Power Down in an Order You Have Verified
Phase 5: Decide Every Asset's Fate Before It Leaves the Rack
- Redeploy internally, to another site or another team.
- Resell into the secondary market for recovery value.
- Recycle through a certified processor when the unit has no resale value.
- Destroy when the risk profile or the contract requires it.
Phase 6: Strip the Facility, Not Only the Racks
- DNS records, firewall rules, load balancer pools, and IP address allocations.
- Monitoring checks, alerting rules, and dashboards that will otherwise page somebody at three in the morning about a machine that no longer exists.
- Software licences, support contracts, and maintenance agreements that keep billing until somebody cancels them.
- Backup jobs and retention policies pointed at storage that has been shredded.
- Documentation, runbooks, and the CMDB records themselves.
Hand finance a closing pack with asset outcomes, so that write-offs and any recovery revenue land in the right period. Archive the audit pack somewhere durable, with the certificates, the chain of custody records, and the reconciliation, and make sure the retention period on that archive matches your regulatory obligation rather than the default your document system applies.
The Sequencing Errors That Cost the Most
Four failures account for most of the pain I have seen, and all four are ordering problems rather than technical ones.
Starting the inventory after the migration plan is written. The inventory drives the plan, so a plan built on a stale asset register will be rewritten at least twice.
Removing hardware before the soak period ends. The schedule pressure is real, and doing it anyway removes your only rollback.
Deciding disposition after equipment reaches the loading dock. By then you are paying to store and move gear whose fate is undecided, and its resale value is falling while you decide.
Treating documentation as a closing task. Chain of custody records have to be created at each handoff. They cannot be reconstructed afterwards, and a reconstructed record is worth very little in an audit.
Key Takeaways
Fix the exit date, the contractual scope, and the named approvers before any other planning starts, because approval authority sits on the critical path more often than the physical work does.
Build a serial-level inventory from three independent passes, and expect the configuration database to be wrong. Record ownership status and media type per unit.
Sequence migrations by real dependencies, then hold a soak period of two to four weeks and verify restores before anything is physically removed.
Trace circuits and get the shutdown sequence reviewed and written down. Power and procedural failures are the leading causes of significant outages, and a decommission is precisely the high risk scenario that research describes.
Decide each asset's destination before it leaves the rack, match the sanitization method to the media type, and remember that a wiped drive can be resold while a shredded one cannot.
Budget the facility strip properly, including regulated waste routes for batteries and refrigerants, and check the restoration clause before you scope it.
Close on paper. Reconcile every serial number to an outcome document, retire the DNS, monitoring, licences and contracts, and archive the audit pack for as long as your regulator requires rather than as long as your document system defaults to.
Frequently Asked Questions
Q: What is data center decommissioning?
A: Data center decommissioning is the controlled process of shutting down, removing, sanitizing, and disposing of IT equipment and related infrastructure when a facility or part of it is no longer needed. It also includes documenting the final outcome of every asset.
Q: How long does a data center decommissioning project take?
A: The timeline depends on the size and complexity of the facility, the number of assets, migration requirements, contract deadlines, and equipment disposition plans. Smaller environments may take weeks, while larger data centers can require several months of planning and execution.
Q: What should be done first when planning a data center decommission?
A: Start by fixing the exit date, defining the contractual and physical scope, and identifying everyone responsible for approvals. Then build a complete, serial-level inventory before finalizing migration, removal, or disposal schedules.
Q: Why is an accurate asset inventory important?
A: A serial-level inventory allows the team to track ownership, workload status, storage media, and the final destination of every asset. It also makes it possible to reconcile equipment with destruction certificates, recycling records, resale settlements, or redeployment records after the project is complete.
Q: How long should equipment remain in place after migration?
A: A defined soak period should be allowed after each migration wave. Two to four weeks is common, giving teams time to identify problems that may only appear during month-end processing, scheduled jobs, reporting cycles, or other less frequent workloads.
Q: What is IT asset disposition (ITAD)?
A: IT asset disposition, or ITAD, is the process of managing hardware after it is removed from service. It can include testing, data sanitization, resale, internal redeployment, recycling, or destruction, along with documentation for each asset.
Q: Can all data center drives be degaussed?
A: No. Degaussing is designed for magnetic media such as traditional hard disk drives and magnetic tape. Solid-state drives use flash memory and require an appropriate sanitization method, such as a supported secure erase process or cryptographic erase.
Q: Should data center equipment be wiped or physically destroyed?
A: That depends on the media, data sensitivity, applicable policies, and contractual or regulatory requirements. Equipment that can be securely sanitized may retain resale value, while equipment requiring physical destruction will generally be treated as scrap after destruction.
Q: What is chain of custody in data center decommissioning?
A: Chain of custody is the documented record of an asset's movement from the time it is removed from the rack until it is redeployed, resold, recycled, or destroyed. Maintaining this record helps demonstrate that assets and their data were handled according to the required process.
Q: What happens to equipment after it is removed from a data center?
A: Each asset should have a predetermined destination. It may be redeployed internally, resold, sent to a certified recycler, or physically destroyed, depending on its condition, ownership, data, and security requirements.
Q: What facility equipment needs to be removed during decommissioning?
A: Depending on the contract and ownership, removal may include structured cabling, cabinets, cage mesh, power distribution equipment, UPS systems, batteries, cooling equipment, containment panels, raised flooring, and other infrastructure installed by the organization.
Q: Why is communication important during a data center decommission?
A: Decommissioning involves multiple teams, including infrastructure, application owners, security, facilities, finance, compliance, and external vendors. Keeping decisions, approvals, dependencies, and schedule changes visible to the right people helps prevent delays and accidental shutdowns.
Q: What documentation should be completed after decommissioning?
A: The closing documentation should include the final asset reconciliation, destruction certificates, recycling records, resale settlements, redeployment records, chain of custody documentation, and relevant approvals. The logical environment should also be reviewed for retired DNS records, monitoring alerts, licences, contracts, and backup jobs.
Q: What is the biggest mistake to avoid during a data center decommission?
A: One of the biggest mistakes is removing equipment before migration has been fully verified. Other costly mistakes include starting with an inaccurate inventory, deciding asset disposition too late, and treating chain-of-custody documentation as something that can be completed at the end.